
Quick Takeaways
- Scoring model drift happens quietly, with no built-in alarm.
- Buyer behavior shifts faster than most scoring weights update.
- Lead score accuracy erodes months before anyone questions the number.
- Scoring model decay is a data problem, not a flaw.
- Catching drift takes a recurring audit, not a smarter algorithm.
- Compare scored leads against closed deals on a fixed schedule.
Table of Contents
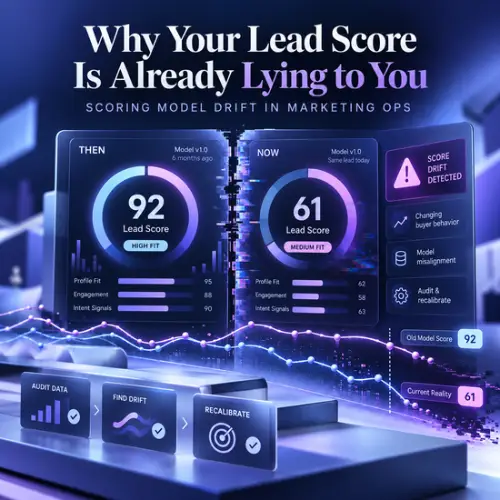
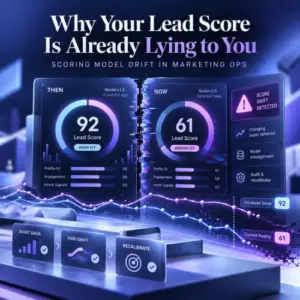
The lead that scored 92 last quarter would score 61 today under the exact same model, recalculated daily against rules nobody has rewritten. That gap is scoring model drift, and it is already sitting inside whatever scoring model your team is running right now, in Eloqua, Marketo, or another platform.
It happens because buyer behavior moves and the weights behind the score do not move with it. A field that used to signal intent, a demo request, a pricing page visit, a specific job title, can lose predictive value in a single quarter, and the model keeps scoring it the same way regardless. Nothing in the platform interrupts to say the math has stopped matching reality.
Therefore, catching scoring model drift before it erodes lead score accuracy is not a feature you turn on automatically. It is a recurring, human-run audit discipline, the kind most teams skip because the dashboard still renders a clean number every morning. For the broader framework this audit discipline sits inside, see our pillar piece on how AI is rewriting lead scoring and grading for marketing ops.
What Scoring Model Drift Actually Looks Like Inside a Live Model
Scoring model drift is the gap between what a scoring model rewards and what actually predicts a closed deal today. It builds slowly: a signal that correlated with intent a year ago quietly stops correlating, while the point value assigned to it in the model stays exactly where it was set.
The Score Stops Tracking the Buyer
Why it matters: A prospect who downloads three data sheets used to signal real intent. Now the same behavior might just mean a researcher is building a competitive comparison for someone else’s project, and the score doesn’t know the difference, so it keeps handing that contact the same points it always has.
Scoring model decay shows up first as a mismatch Sales notices before Marketing does: reps start ignoring high-scored leads because the last several didn’t convert, and the score’s credibility erodes long before anyone traces the problem back to the model itself.
Where Drift Hides in Eloqua, Marketo, or Another Platform
In Eloqua, the score lives on the Contact record, built from profile criteria that get set once and rarely revisited. Eloqua recalculates that score on its normal schedule and ages point values down through decay settings, but neither process ever asks whether the criteria and point values themselves still deserve the weight they were given.
In Marketo, the same risk sits inside the Person record’s scoring rules, often built years earlier by someone no longer on the team. Whichever platform holds the model, the underlying failure is identical: nobody owns the job of asking whether the point values still mean what they meant when someone configured them. Our piece on how Eloqua and Marketo differ on native data quality tooling is a useful starting point for understanding where each platform leaves this gap for a team to fill itself.
Why No Alarm Goes Off When Scoring Model Decay Sets In
No platform pings a marketing ops team to say the scoring model stopped matching reality. That silence is the actual danger, not the drift itself, because a model that fails loudly gets fixed fast, and a model that fails quietly keeps producing confident, wrong answers for months.
The Backtesting Gap Nobody’s Closing Automatically
The honest answer to “why doesn’t something just warn me when my score drifts” is that no AI system, including ours, currently runs automatic backtesting: the process of re-running a current scoring model against historical closed-won and closed-lost data to see whether it would have scored those deals correctly. That is not a capability 4Thought Marketing offers today, and treating drift detection as something AI will eventually do on its own is exactly the assumption that lets it run unchecked for a full sales cycle or longer.
Why it matters: backtesting is the check that would catch scoring model drift early, and right now it has to be run by a person, on a schedule, against real outcome data, not by a model watching itself.
What a Recurring Audit Has to Check That AI Won’t
A recurring audit compares scored leads against what Sales actually closed, updates point values for signals that no longer predict, and retires criteria that have quietly gone stale. None of that happens by default inside a scoring model; someone has to pull the comparison and decide what changes. Oracle’s documentation on viewing a contact’s lead score history is a practical starting point for pulling the raw data this kind of audit needs before drawing any conclusions.
Building the Audit Discipline Before Sales Notices First
Waiting for Sales to flag a bad lead score is the most expensive way to discover scoring model drift, because by the time reps stop trusting the number, the damage to pipeline has already accumulated for a quarter or more.
Set a Fixed Cadence, Not a Reactive One
Set a recurring audit on the calendar, quarterly at minimum, and run it whether or not anyone has complained. A model that looks fine on the dashboard can still be actively decaying, and that kind of drift rarely announces itself before it shows up in a rep’s closed-lost notes.
Compare the Model Against What Actually Closed
Pull a sample of scored leads from the last two quarters and check what they actually did: did the high scores close, did low scores convert anyway, and where did the model miss in both directions. Adobe’s guide to reporting on your revenue model is a solid reference for pulling the closed-deal data a Marketo instance needs to run this comparison; Eloqua teams can build the equivalent pull from Contact and opportunity records. This comparison is the closest a team gets to backtesting without an automated tool doing it, and right now, doing it manually is the only version that exists.
Where Scoring Model Drift Compounds With Everything Else Touching the Score
It rarely stays contained to the score itself. Scoring model drift compounds with every other system and process that reads from that number, which is why the audit habit has to extend past the scoring model alone.
When the Data Feeding the Score Is Already Broken
An undetected sync failure between your CRM and your marketing automation platform can look identical to scoring model drift from the outside; both produce a score Sales stops trusting, for entirely different underlying reasons. Our piece on Eloqua-Salesforce integration failures that go undetected for months walks through how to tell the two apart before assuming the model itself is the problem. A related but distinct cause is blended lead scoring data that was never fully reconciled in the first place, where signals from separate systems get treated as one profile without a documented source-of-truth hierarchy.
Where Drift Spreads Beyond a Single Score
If your team is layering AI agents on top of the scoring process itself, drift becomes harder to catch, not easier, because an agent acting on a stale score just executes the wrong decision faster. Our guide to governing AI agents that touch a contact’s score covers the oversight a team needs before letting automation act on a number nobody has recently audited.
Score decay doesn’t stay isolated to MQL scoring either. Marketo nurture programs built on the same point logic inherit the same problem, which is exactly what we cover in our piece on score decay in a Marketo nurture program. And once a score feeds account-level prioritization instead of just individual leads, the same undetected drift can misdirect an entire ABM motion; see our piece on AI account prioritization for how that risk shows up at the account tier.
None of this is unique to lead scoring. Our broader look at AI-powered predictive signals covers the same blind-spot pattern across other AI-assisted marketing ops processes; scoring model drift is simply the clearest version of it.
Conclusion
The score on your dashboard right now might already be wrong, not because anyone built it badly, but because scoring model drift is what happens to any model nobody re-checks against real outcomes. AI can score faster and more consistently than a person ever could, but it cannot tell you when the math it is running no longer matches how your buyers actually behave; that check still has to come from a person, on a schedule, backed by real closed-deal data.
Teams that build a recurring audit around lead score accuracy catch scoring model decay while it is still a minor correction; teams that wait find out when a quarter of pipeline already went cold on a lead the model was confidently wrong about. If you want help building that audit discipline into your own Eloqua, Marketo, or other platform’s scoring process, contact us and we will start with the last quarter of closed deals your current model got wrong.
About 4Thought Marketing
We're a B2B marketing automation and AI consultancy with a thing for getting complex tech to actually work. Since 2008, we've helped hundreds of organizations across financial services, technology, manufacturing, and real estate get more from Eloqua, Marketo, and their CRM integrations. We serve our clients across marketing automation strategy, lead lifecycle, AI, compliance, preference management, and more. Explore our services or get in touch.
Frequently Asked Questions
What is scoring model drift?
Scoring model drift is the gap that opens up when a lead scoring model keeps assigning the same point values to signals that no longer predict buyer intent the way they once did. It happens gradually and without any built-in alert, which is why most teams only notice it after Sales stops trusting the score.
Why doesn’t something just warn me automatically when my score drifts?
Because automatic backtesting, running your current scoring model against historical closed-won and closed-lost data to check whether it still scores correctly, is not something AI does on its own today, including inside 4Thought Marketing’s current AI capabilities. Catching scoring model drift right now requires a person to run that comparison on a recurring schedule; treating it as a problem AI will eventually flag by itself is how drift goes undetected for months.
How is gradual model decay different from a bad initial scoring model?
A bad initial model is wrong from the start. Scoring model decay is a model that was accurate when it launched and has since drifted out of alignment as buyer behavior changed around it, so the fix is a recurring audit against real outcomes, not automatically a full rebuild.
How often should a team audit for this kind of drift?
Quarterly at minimum, and sooner if Sales starts flagging inconsistent lead quality. Waiting for a complaint usually means the drift has already been compounding for a full sales cycle, longer than most teams can afford before it shows up in pipeline numbers.
What actually protects the score’s accuracy over time?
A documented, recurring comparison between what the model scored and what Sales actually closed, run on a fixed cadence rather than only when something looks wrong. Retiring signals that no longer predict and updating point values for ones that do is what keeps lead score accuracy intact as buyer behavior changes.
Does scoring model drift affect both Eloqua and Marketo environments?
Yes. Eloqua’s Contact-level scoring and Marketo’s Person-level scoring rules both rely on point values set at a point in time and rarely revisited, so both platforms carry the same risk. The mechanics of where the score lives differ by platform, but the audit discipline needed to catch drift is identical.